
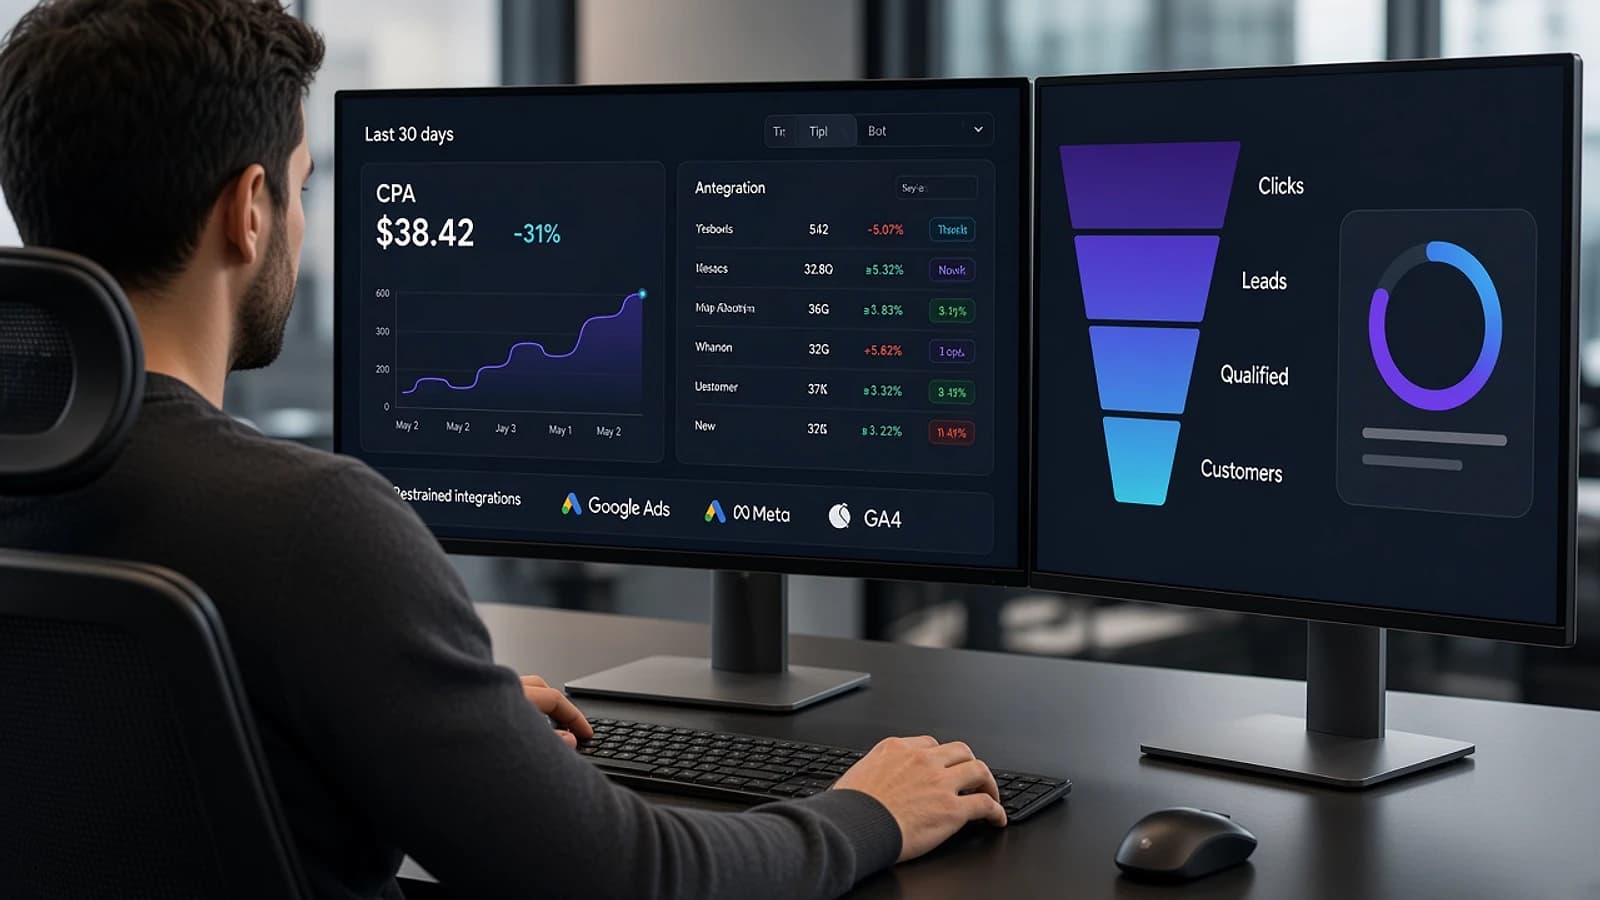
Performance funnel rebuild
A B2B services company needed acquisition it could trust. We fixed tracking first, then scaled Meta and Google against true cost per acquisition.
- Location
- Remote / EU
- Project
- Performance Marketing
- Industry
- B2B Services
Systematic prompt design, evaluation sets, and model routing — so quality goes up and spend goes down.
 Syed Wajeeh ul Hassan
 Harris Khan
 Bassam Hashmi
Working with businesses across the US, UK, Europe and Australia
Automate — AI & Engineering
We build golden sets, compare prompts and models, and document the winners so your team can iterate without guesswork.
How we work
We learn what you sell, who buys it and what is working now. No proposal before this conversation.
We audit traffic, tracking, funnel and systems, then name the real constraint on growth.
A scoped plan with clear deliverables, timelines and the numbers we will be judged on.
We execute in the open, report on what matters, fund what is proven and cut what is not.
Case Studies
A B2B services company needed acquisition it could trust. We fixed tracking first, then scaled Meta and Google against true cost per acquisition.
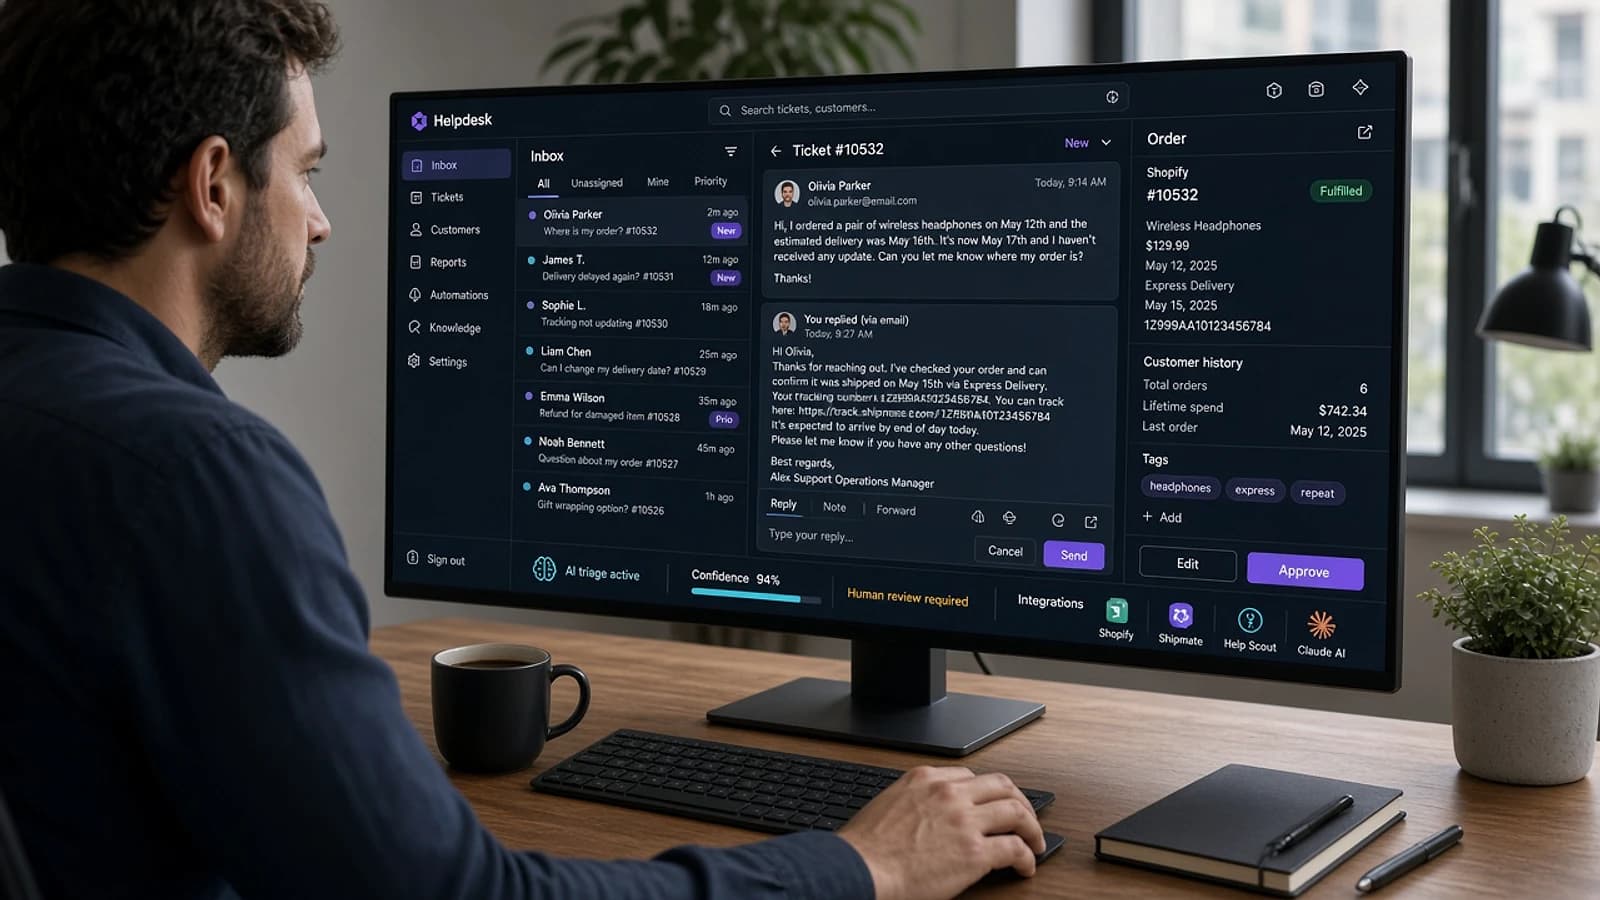
An online retailer needed to scale customer support without adding headcount. We automated triage and drafted replies with brand context built in.
Development
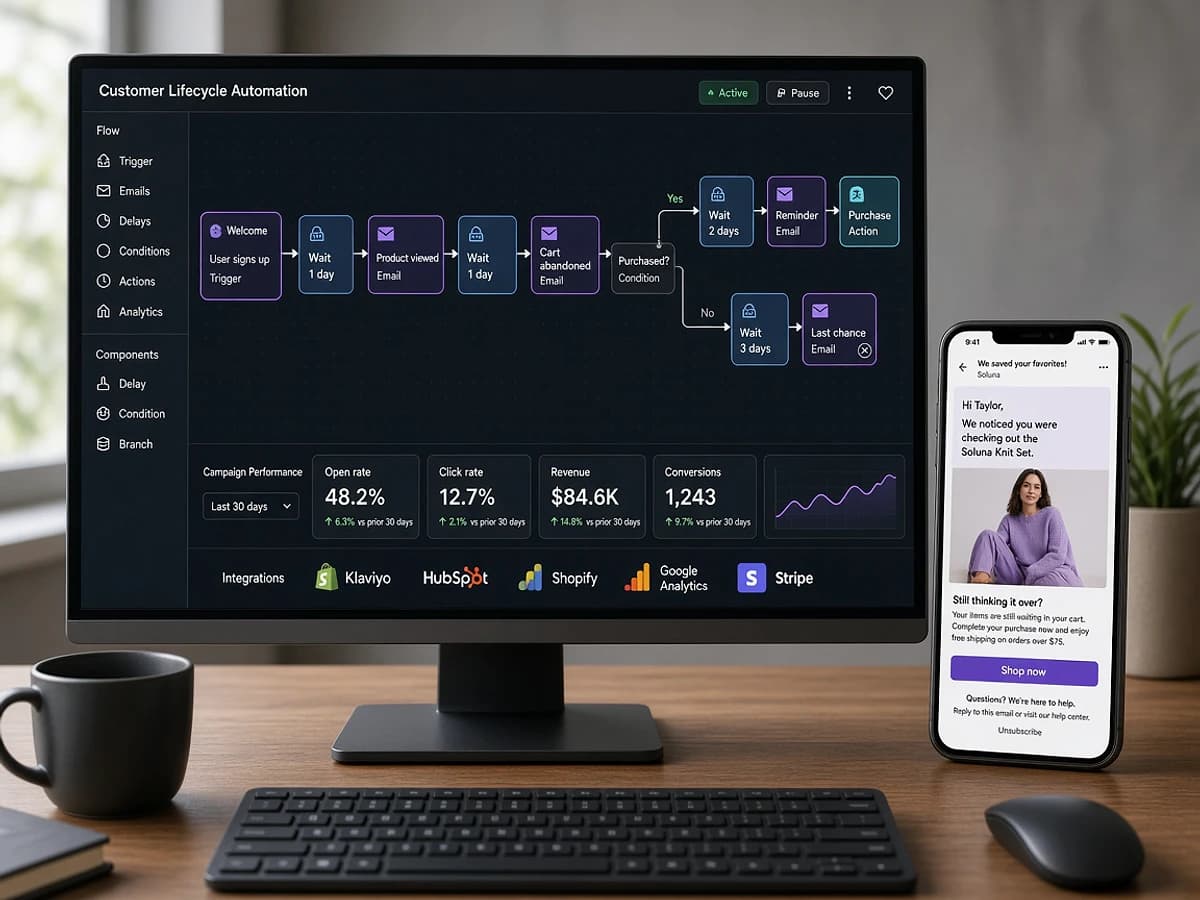
Digital Marketing
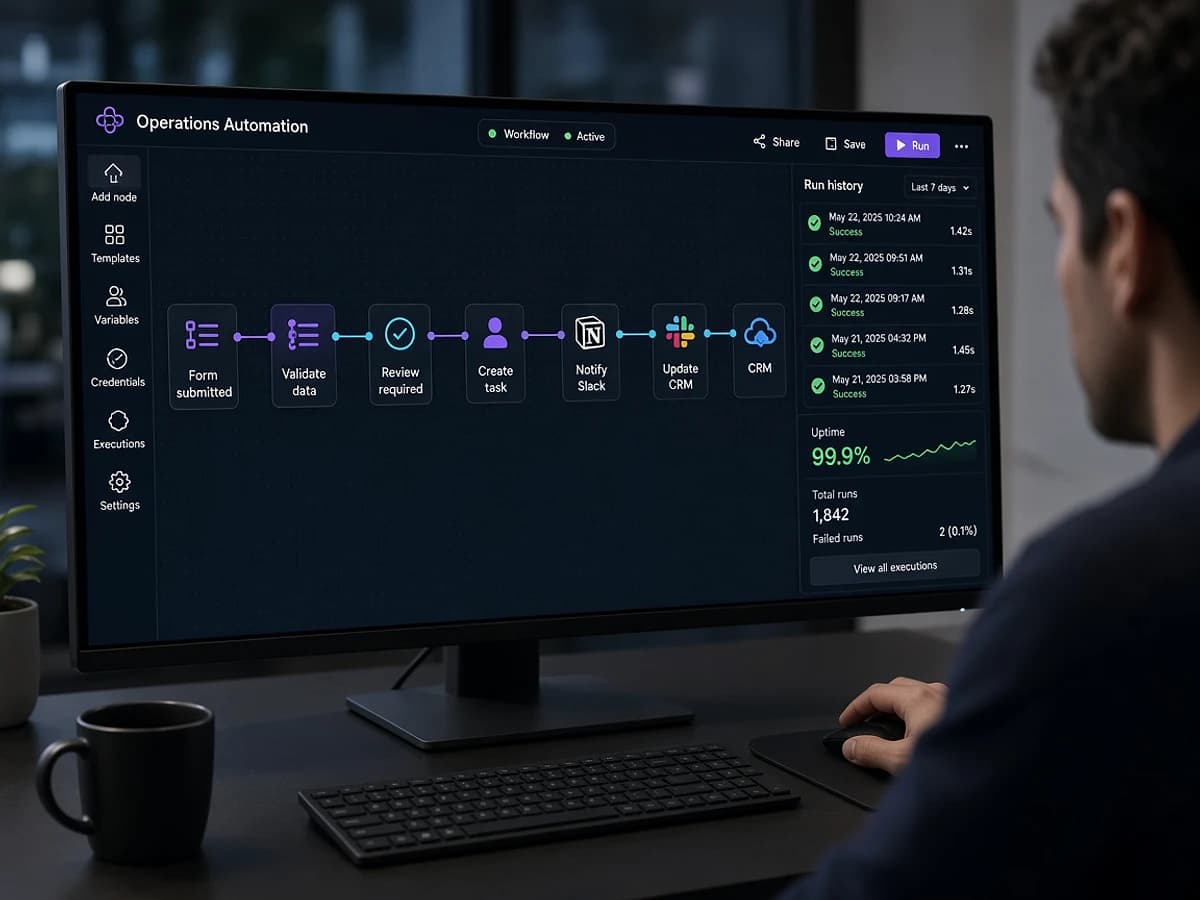
AI Automation
Client feedback
“They redesigned our internal workflows with automation and delivered measurable efficiency, without overselling what AI could do.”

Michael Carter
Chief Technology Officer
“Support operations became dramatically more efficient after the conversational system went live. Clear scope, honest reporting.”

Sophia Bennett
Head of Operations
“They tied paid spend to pipeline we could actually trust. The monthly report finally answered whether the marketing made money.”

Daniel Hughes
Director of Growth
FAQ
Designing the instructions given to a language model so it produces accurate, consistent output for a specific task. It covers structure, examples, constraints, output format and the way context is provided.
With an evaluation set: real inputs paired with the output you want. We score the current prompt, make changes and rescore. Improvement is a number, not an opinion.
Often, yes. Shorter, better-structured prompts use fewer tokens, and a well-prompted smaller model can replace a larger one for many tasks.
OpenAI, Anthropic, Google and open-source models. We test the same evaluation set across providers and recommend based on accuracy and cost for your task.
Yes. You receive a documented prompt library with the evaluation set, so your team can maintain and extend it.


A 30-minute call. We will look at your current setup and tell you where the biggest gap is — whether or not you work with us.